SaaSCloud HostingIT security and risks17 min czas czytania21 530 znaków3253 słowa
SLA — what it is and what to check in an SLA with a cloud provider
SLA meaning: how much downtime fits in 99.9%, how AWS, Microsoft and Google SLAs compare, SLO, RPO, RTO and 10 things to check before signing.
Redakcja Digital VantageYour Partner in Business, Digital Vantage Team · Digital Vantage team is a group of experienced professionals combining expertise in web development, software engineering, DevOps, UX/UI design and digital marketing. Together we carry out projects from concept to implementation - websites, e-commerce stores, dedicated applications and digital strategies.
Our team combines years of experience from technology corporations with the flexibility and immediacy of working in a smaller, close-knit structure. We work in agile methodologies, focus on transparent communication and treat each project as if it were our own business.
The strength of the team is the diversity of perspectives - from systems architecture and infrastructure, frontend and design, to SEO and content marketing strategy. As a result, the client receives a cohesive solution where technology, aesthetics and business goals go hand in hand.
Publikacja
Aktualizacja
SLA — what does it mean, and why does it show up in every contract with a cloud provider? The term stands for service level agreement: a document in which a provider writes down how well its service is supposed to work, and what happens if it doesn't keep its word. In cloud and SaaS services, this usually comes down to one number — a monthly uptime percentage, say 99.9%. That number sounds like a promise that the service will almost never go down. In practice it means something far more modest.
This article covers the SLAs of cloud providers, SaaS software and IT services your company relies on: e-mail, office suites, cloud servers. We show how much downtime typical SLA levels actually allow, how AWS, Microsoft and Google's agreements compare, how SLA differs from SLO, what RPO and RTO mean, and how an SLA sits against Swiss contract law. At the end you'll find a list of 10 things to check before you sign. If you're looking for a service contract for a company website rather than a cloud service, that's a separate topic covered in our article on website maintenance.
SLA meaning — the definition, and what an SLA is not
The most precise definition you can read for free comes from the ISO/IEC 17788:2014 standard, published in parallel by the ITU as Recommendation Y.3500. In point 3.1.7 it adopts a definition from the service-management standard ISO/IEC 20000-1 (ITU-T Y.3500, 08/2014):
> "service level agreement (SLA): Documented agreement between the service provider and customer that identifies services and service targets."
In other words: a service level agreement is a documented agreement between a provider and a customer that identifies the services and their targets. Two notes attached to this definition matter just as much in practice. First: an SLA can also apply between a provider and its subcontractor, or an internal department. Second: an SLA "can be included in a contract or another type of documented agreement". In the cloud it's usually a separate document that the terms of service refer to, and that the provider can update.
Microsoft's own guide to reading an SLA puts it more practically: an SLA is "a contractual commitment between a service provider and a customer, with defined consequences for unmet targets", and at the same time "a set of conditional commitments" (Microsoft Learn, 31.03.2026). The word "conditional" is the key to the whole topic.
What an SLA is not. An SLA is not a guarantee that a service won't fail. The provider doesn't promise an outage won't happen — it promises what it will do if an outage exceeds an agreed limit. In the cloud, that consequence is almost always a service credit: a discount on a future bill, not a payout. Microsoft states this outright: "Credits don't cover lost revenue, customer attrition, or reputational damage", and providers "don't usually apply them automatically".
How much downtime fits in 99.9% — uptime in minutes
Uptime in an SLA is the percentage of time a service is up, measured over a given period. The allowed downtime follows a simple formula:
allowed downtime = (1 − SLA / 100) × minutes in the period
A 30-day month has 43,200 minutes, a 365-day year 525,600 minutes. For 99.9% in a month, that comes to 0.001 × 43,200 = 43.2 minutes. The table below shows typical levels (our own calculations):
SLA level | Downtime per month (30 days) | Downtime per year (365 days) |
|---|---|---|
99% | 432 min (7.2 h) | 87.6 h |
99.5% | 216 min (3.6 h) | 43.8 h |
99.9% | 43.2 min | 8.76 h |
99.95% | 21.6 min | 4.38 h |
99.99% | 4.32 min | 0.88 h (about 53 min) |
How much downtime fits inside an SLA
Our own calculations: (1 − SLA/100) × 43,200 min (30 days) or 525,600 min (365 days)
Two things follow from this table. First, the gap between "two nines" and "four nines" is the gap between over seven hours and four minutes a month — these are not cosmetic improvements. Second, providers measure uptime over a month, not in real time. Microsoft Learn: "SLAs usually measure uptime over a billing period, not in real time". The annual 8.76-hour figure for 99.9% is therefore just an illustrative conversion. A provider can stay within its SLA every month, and a single 40-minute outage at the wrong moment — say, on month-end closing day — can still stop your business cold.
The table also doesn't show what the provider counts as downtime — and exclusions and the definition of "unavailability" can make the real-world outage longer than the one in the SLA statistics.
How the big providers' SLAs actually read
Below are three documents in the versions we read: AWS and Google on 30 September 2026, Microsoft's October 2026 edition on 2 October 2026.
AWS: Amazon Compute SLA (EC2)
The document for EC2 virtual servers is dated "Last Updated: May 25, 2022" (AWS). It contains two commitment levels:
- 99.99% at the region level — applies to instances deployed across at least two availability zones;
- 99.5% at the single-instance level.
Compensation is a percentage of fees: for the region, 10% below 99.99% but at least 99.0%; 30% below 99.0% but at least 95.0%; 100% below 95.0%. For a single instance, the first threshold is the range from 99.0% up to but below 99.5%, with the other tiers the same. AWS also doesn't charge for a single instance that's unavailable for more than six minutes in a given clock hour — the only part of this that applies automatically.
Everything else you have to claim yourself. A credit is granted after a request filed in the AWS Support Center, which must arrive by the end of the second billing cycle after the incident. The credit is only issued if it exceeds one dollar, and it can only be applied to future payments: "Service Credits will not entitle you to any refund". The SLA excludes, among other things, unavailability caused by force majeure, internet problems outside the boundary of AWS's EC2 infrastructure, and the customer's own acts, omissions, hardware or software. The most important sentence comes at the end: the SLA sets out "your sole and exclusive remedies" for unavailability.
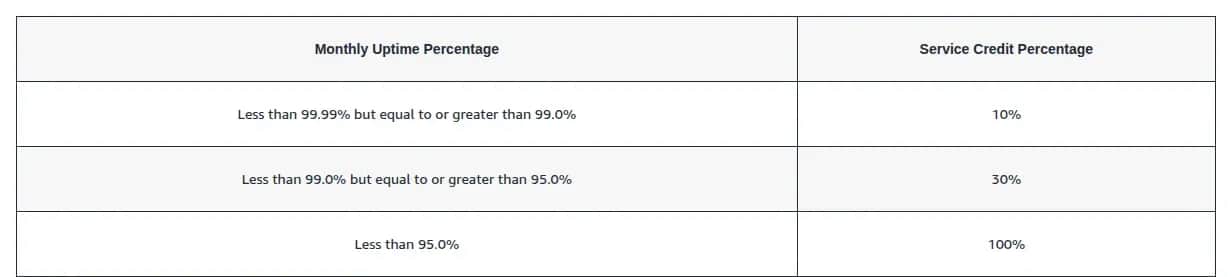
Amazon EC2 SLA credit table (region level)
aws.amazon.com/compute/sla, screenshot of 2026-09-30
Microsoft: Service Level Agreement for Online Services
Microsoft publishes a consolidated document covering its online services: the "Service Level Agreement for Microsoft Online Services, October 1, 2026" (Microsoft, SLA for Online Services). Its sole-remedy clause reads: "Service Credits are your sole and exclusive remedy for any performance or availability issues for any Service under the Agreement and this SLA. You may not unilaterally offset your Applicable Service Fees for any performance or availability issues."
The document adds that credits will "not, under any circumstance, exceed your monthly service fees for that Service", and will not be awarded to compensate for other losses, "including but not limited to lost revenue, operational costs, or any indirect losses experienced by you or the end-users".
The exclusion for scheduled maintenance matters too. "Scheduled Downtime" is downtime related to network, hardware or service maintenance or upgrades, about which the document says: "We will publish notice or notify you at least five (5) days prior to the commencement of such Downtime." That downtime doesn't count toward the SLA's downtime. For some services Microsoft drops this exclusion: for Exchange Online, the document states that "there is no Scheduled Downtime for this service".
Levels for the services most companies rely on: Exchange Online and Teams — 99.9%, with a 25% credit below 99.9%, 50% below 99% and 100% below 95%. For Exchange, downtime means a period in which users can't send or receive e-mail via Outlook Web Access. The claim deadline for Azure is 60 days from the incident; for other services, the end of the billing period following the month of the incident; processing typically takes up to 45 days. Preview versions and free plans aren't covered by the SLA.
Google Workspace SLA
Google's document is dated "Last modified: August 31, 2026" (Google Workspace SLA). The commitment: monthly availability "at least 99.9% in any calendar month".
Google calculates compensation differently from AWS and Microsoft — in days of service: 3 days below 99.9% (but at least 99.0%), 7 days below 99.0% (at least 95.0%) and 15 days below 95.0%. The total credit in a month can't exceed 15 days. Customers billed offline by invoice get the days added at the end of the contract period; customers paying online get a monetary credit equal to those days on a future invoice.
Downtime is a period in which the service's web interface has more than five percent user errors. A claim has to be filed within 30 days of the moment the customer became eligible for the credit — after that, the right lapses. Here too, the SLA is the customer's "sole and exclusive remedy". One detail: the document contains no scheduled-maintenance exclusion at all.
AWS, Microsoft and Google SLA compensation
AWS Amazon Compute SLA (25.05.2022), Microsoft Online Services SLA (1.10.2026), Google Workspace SLA (31.08.2026); read 2026-09-30 and 2026-10-02
What all three documents share. Compensation takes the form of a credit against future service, you have to claim it within a set deadline, it has an upper limit, and it's the only remedy the agreement provides. A credit worth even 100% of a month's e-mail fee is usually a fraction of what a day without e-mail actually costs your business.
Google Workspace status dashboard — the public availability report
google.com/appsstatus/dashboard, screenshot of 2026-09-30
SLA vs SLO vs SLI — three terms that are easy to mix up
Alongside SLA, two other abbreviations come up in reliability conversations. The most widely cited definitions come from Google's Site Reliability Engineering book, in its chapter on service level objectives (Google SRE Book):
- SLI — "An SLI is a service level indicator—a carefully defined quantitative measure of some aspect of the level of service that is provided." In practice: the share of successful requests, or response time, for example.
- SLO — "An SLO is a service level objective: a target value or range of values for a service level that is measured by an SLI."
- SLA — "SLAs are service level agreements: an explicit or implicit contract with your users that includes consequences of meeting (or missing) the SLOs they contain."
The authors offer a simple test: ask "what happens if the SLOs aren't met?". If there's no clear consequence, you're almost certainly looking at an SLO, not an SLA.
For a customer, this distinction has practical weight: a statement like "we aim for 99.95% availability" describes an SLO — a target. What actually binds the provider is the document that ties the number to a consequence.
RPO and RTO — how much data and how much time you can lose
An SLA talks about availability: how long a service can be down. It says nothing about how much data you'll lose after a serious outage, or how fast you'll be back up after a disaster. Two other terms cover that, best described in NIST SP 800-34 Rev. 1, the publication on IT contingency planning, in its section on business impact analysis (NIST SP 800-34 Rev. 1, May 2010, p. 17):
> "Recovery Time Objective (RTO). RTO defines the maximum amount of time that a system resource can remain unavailable before there is an unacceptable impact on other system resources, supported mission/business processes, and the MTD."
RTO (recovery time objective) is the maximum time a system resource can stay unavailable before the impact on other resources, supported business processes and the MTD — the maximum tolerable downtime of a business process — becomes unacceptable.
> "Recovery Point Objective (RPO). The RPO represents the point in time, prior to a disruption or system outage, to which mission/business process data can be recovered (given the most recent backup copy of the data) after an outage."
RPO (recovery point objective) is the point in time before a disruption or outage to which business process data can be restored, based on the most recent backup. NIST adds that RPO expresses how much data loss a business process can tolerate.
In short: RTO answers "how long", RPO answers "from what point". If a backup runs once a day, RPO is, in the worst case, 24 hours: anything entered since the last backup has to be re-entered by hand, or is simply lost. None of the three SLAs described above contains RPO or RTO commitments for customer data — they talk about service availability, not about recovering your data. Those parameters have to be set separately, or guaranteed yourself. How to plan backups and recovery for a website is covered in our article on backup and recovery.
SLAs and Swiss law
An SLA with a foreign provider is governed by the law named in the main contract, but the Swiss reference point for liability questions is the Code of Obligations. Art. 97(1): "An obligor who fails to discharge an obligation at all or as required must make amends for the resulting damage unless he can prove that he was not at fault." Without any SLA at all, a provider would therefore already be liable, on general principles, for damage caused by defective performance — unless it proves it was not at fault.
Art. 100(1) goes further than the general rule: "Any agreement purporting to exclude liability for unlawful intent or gross negligence in advance is void." Note that it covers gross negligence, not just intent. Clauses like "the credit is the sole remedy" limit liability — and Art. 100 sets a floor below which such limits don't hold.
On contractual penalties, Art. 160(1) provides that where a penalty is promised for non-performance or defective performance, "unless otherwise agreed, the creditor may only compel performance or claim the penalty"; Art. 161(1): "The penalty is payable even if the creditor has not suffered any damage", with further damages only if the debtor was at fault (161(2)). Art. 163(3): the court reduces penalties it considers excessive.
Is a service credit a contractual penalty (Konventionalstrafe)? We stop here deliberately. A credit resembles a contractual penalty — a pre-set amount for defective performance — but it takes the form of a discount on future fees rather than payment of a specified sum. We haven't found a source that settles this one way or the other. If a meaningful share of your company's revenue depends on a service's availability, this is exactly the question to put to a lawyer before you sign — together with the question of governing law and jurisdiction.
DORA — doesn't apply here. Regulation (EU) 2022/2554 covers EU financial entities and their ICT contracts; it has no direct application in Switzerland. FINMA has its own outsourcing rules, but we haven't read their content here, so we won't cite it — if your SLA sits inside a regulated financial activity, check FINMA's circulars directly.
The Swiss counterpart to NIS2. Switzerland's reporting duty sits in the Information Security Act (ISG, SR 128): in force since 1 April 2025, with fines possible from 1 October 2025, it requires a report to the National Cyber Security Centre (NCSC) within 24 hours of certain incidents, and cloud and data-centre providers with a Swiss seat are among the obliged entities. This is a reporting duty, not NIS2's full risk-management regime — a narrower obligation than the EU directive it's sometimes compared to.
10 things to check in an SLA before you sign
Everything above comes down to a checklist. It applies to any SLA — with a large cloud provider, a smaller SaaS company, or an IT services provider:
- Exclusions. What doesn't count as downtime: force majeure, internet problems, the customer's own actions, account suspension. The wider the list, the less the nines are worth.
- Scheduled maintenance. Is it excluded from the availability calculation, how much notice does the provider give (at least 5 days with Microsoft) and is there a cap on its length? Some providers don't exclude it at all.
- How availability is measured. What exactly counts as "unavailable": no server response, an error rate (above 5% with Google), the inability to send e-mail? Over what period is the percentage calculated — a calendar month or a billing period?
- Claim deadline and format. AWS: by the end of the second billing cycle. Google: 30 days. Microsoft, for Azure: 60 days. Credits usually aren't applied automatically — someone at your company has to track and file claims.
- Compensation cap. Usually 100% of a month's service fee (Microsoft) or 15 days of service (Google) — regardless of how long the outage actually lasted.
- The sole-remedy clause. Does the SLA state that a credit is the customer's only entitlement? All three providers covered here phrase it that way, which means an SLA doesn't give you a claim for lost revenue.
- Support response time. Availability is one thing; how fast someone responds to an outage report is another. Check whether response times are actually in the agreement, or only on a support-plan pricing page.
- RPO and RTO. Does the provider state from what point, and in how much time, it will restore your data at all? If not, assume you have to guarantee that yourself.
- Availability reports. Does the provider publish a history of availability and incidents, or do you have to measure it yourself just to know you're entitled to a credit?
- Changing provider. What happens to your data after termination, and in what format and timeframe you'll get it back. More on exit strategy is in our article on cloud data security.
SLAs for a small business — what you can negotiate, and what you have to cover yourself
The honest answer is: with a large cloud provider, a small business usually won't negotiate anything. AWS, Microsoft and Google's SLAs are standard documents, accepted together with the terms of service, and changes are published by the provider. Negotiation is realistic mainly with smaller SaaS vendors, local IT companies and custom-software contractors. There it's worth discussing response times, an out-of-hours incident channel, backup parameters, and the format you'll get your data in if you part ways. The choice between a ready-made service and your own system — and the resulting difference in responsibility — is covered in our article on on-premise.
Since a credit won't cover your losses, real protection comes from what the company does on its own. Three things matter most:
- Your own monitoring. If you don't know when a service was down, you won't file a claim in time, and you won't be able to check the provider's own report. Simple external uptime monitoring shows downtime from your perspective, not the provider's statistics. How this works for websites is covered in our article on website monitoring.
- Your own backups. An SLA covers service availability, not your data. A backup kept somewhere other than the service itself is the only way RPO depends on you rather than on the provider — see our article on website backup.
- A plan B for a few hours. For processes that can't stop — order handling, customer contact, payments — it's worth knowing in advance what you'll do if a service is down for half a day: an alternative contact channel, an off-system order list, someone responsible for communicating with customers.
If the SLA you're actually interested in is for a company website rather than a cloud service, you're really talking about a maintenance contract: response time, updates, backups and monitoring. That topic is covered in our article on website maintenance, and the maintenance cost calculator gives a rough idea of what that kind of care costs.
What's next
What cloud computing actually is, and how the IaaS, PaaS and SaaS models differ — and so which layers are covered by a provider's SLA — is explained in our article on cloud computing. More on the SaaS model itself is in our guide to SaaS. If you're choosing a provider for a critical system and want to go through the contract with someone who understands the technical side, see our technology consulting.
FAQ
Frequently asked questions about SLAs
An SLA (service level agreement) is a document in which a service provider writes down how well the service is supposed to work — in the cloud, usually as a monthly uptime percentage, e.g. 99.9% — and what happens if it fails to hit that level. An SLA doesn't guarantee there will be no outages. It only sets out the consequences of exceeding a downtime limit, usually a discount on a future bill.
In a 30-day month, a 99.9% SLA allows 43.2 minutes of downtime, which works out to 8.76 hours a year. The formula: (1 − SLA/100) × minutes in the period. Providers usually calculate availability over a month or billing period, and scheduled maintenance and other exclusions in the agreement often don't count toward downtime.
Usually not in the sense of damages. AWS, Microsoft and Google's SLAs provide a service credit — a percentage of fees or a few days of service, applied to future bills — and state that it's the customer's sole remedy. Microsoft explicitly excludes compensation for lost revenue. A credit has to be claimed within the agreement's deadline. Whether such a credit counts as a contractual penalty under the Code of Obligations is a question for a lawyer.
Per Google SRE, an SLO (service level objective) is a target value for a service level, measured by an SLI. An SLA is the agreement that ties an SLO to consequences for missing it. A simple test: if you don't know what happens when a target isn't met, you're looking at an SLO, not an SLA.
Per NIST SP 800-34, RTO (recovery time objective) is the maximum time a system can stay unavailable before the impact on the business becomes unacceptable. RPO (recovery point objective) is the point before an outage to which data can be restored from the most recent backup — essentially, how much data a business can afford to lose. Cloud providers' SLAs cover service availability and usually contain no RPO or RTO commitments for customer data.
Want to check what your SLA actually guarantees?
We'll go through the agreements your company relies on together: availability, exclusions, backups, and what you need to cover yourself.
Related Posts
- SaaS — what it is and when subscription software makes sense for a business
What SaaS is: software as a service by NIST's definition, real business examples, SaaS vs in-house software, and when a subscription pays off.
- 1.Multi-tenant — what it is and how to choose a SaaS architecture for many customers
Multi-tenant SaaS: single tenant vs multi-tenant, the silo/pool/bridge models, Row Level Security, Swiss data protection and choosing a model for an MVP.
- 2.On premise — what it means and when your own server beats the cloud
On premise, your own server: the full cost beyond hardware, the end of Windows Server 2016 support, and when the cloud or VPS wins instead.
- 3.ARR, MRR and churn — SaaS metrics, formulas, benchmarks and measurement traps
ARR, MRR, churn, NRR, LTV:CAC and Rule of 40: formulas from ChartMogul and Stripe, benchmarks with their sample size, and the traps that make SaaS metrics lie.
- 4.SaaS application — how to build your own product from MVP to recurring payments
A SaaS application from MVP to subscription: the five building blocks, recurring payments in Switzerland, the legal minimum, costs and the DVN Links example.
- 5.Cloud computing — what it is and how IaaS, PaaS and SaaS differ
Cloud computing by the NIST definition: five traits, IaaS, PaaS and SaaS, public, private and hybrid cloud, and how businesses actually use the cloud.
- 6.Micro-SaaS examples 2026 — 35 niche tools you could build
35 micro-SaaS examples grouped by industry, a niche-scoring framework, a 30-day MVP plan, and Swiss VAT for selling abroad.
- 7.Cloud security: who's responsible for what, and what to ask your provider
Cloud security explained: shared responsibility, the processor contract, US data transfers, Switzerland's Information Security Act and your cloud exit strategy.
- 8.Freemium or free trial? The SaaS subscription model in numbers
Freemium, trial without a card, or trial with a card: ChartMogul conversion data, time-to-value, churn, MRR, LTV:CAC and European cloud adoption from Eurostat.
- 1.
About the Team
Digital Vantage Team
Your Partner in Business, Digital Vantage Team
Digital Vantage team is a group of experienced professionals combining expertise in web development, software engineering, DevOps, UX/UI design and digital marketing. Together we carry out projects from concept to implementation - websites, e-commerce stores, dedicated applications and digital strategies. Our team combines years of experience from technology corporations with the flexibility and immediacy of working in a smaller, close-knit structure. We work in agile methodologies, focus on transparent communication and treat each project as if it were our own business. The strength of the team is the diversity of perspectives - from systems architecture and infrastructure, frontend and design, to SEO and content marketing strategy. As a result, the client receives a cohesive solution where technology, aesthetics and business goals go hand in hand.